Real World Inc.
展商:RLWRLD
原产国/地区:美国
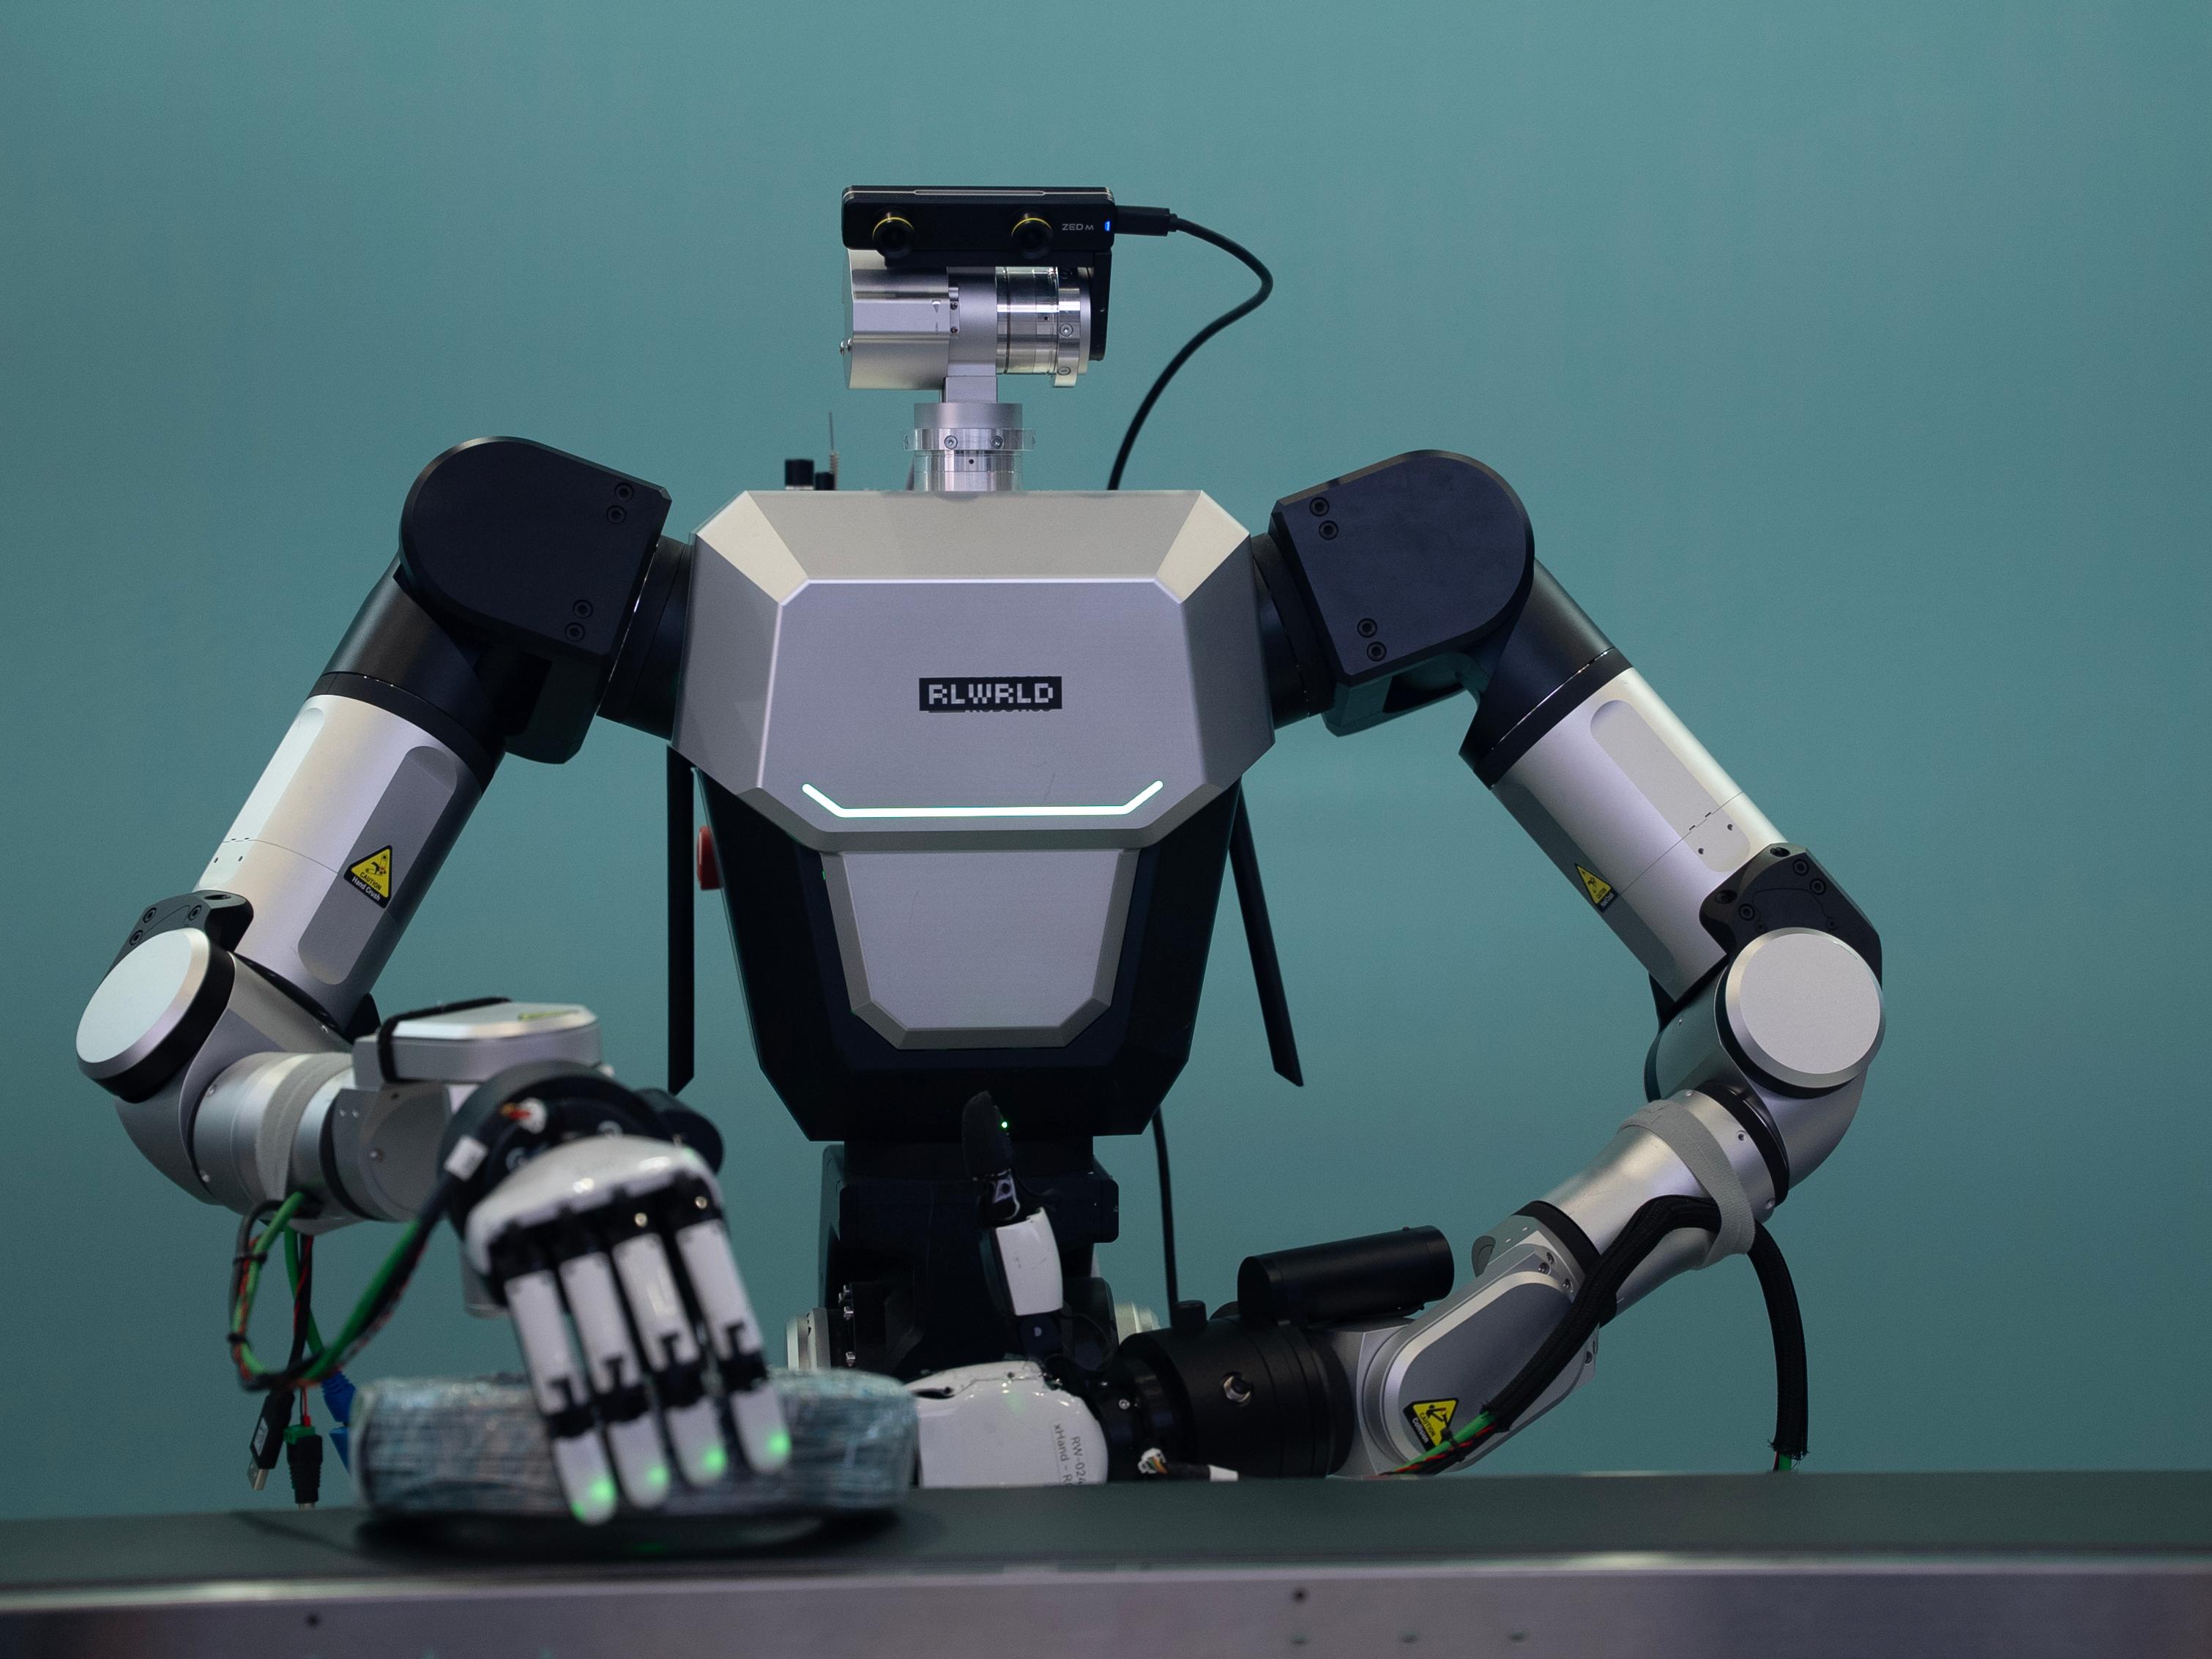
Material/Composition: RLDX-1, RLWRLD's dexterity-first RFM, deployed on an RB-Y1 arm with dual RoboEra X-Hands, multi-camera vision, and on-site GPU inference. Technical Specifications: Built on MSAT (Multi-Stream Action Transformer), processing vision-language, proprioception, tactile, torque, and memory as separate streams fused via self-attention. Embodiment-agnostic training and graceful sensor degradation let one model run across single-arm, dual-arm, and humanoid platforms (validated on Franka Research 3, ALLEX, OpenArm) without hardware-specific retraining. Core Purpose: Shows RLDX-1 is not tied to one robot body — the same model, redeployed on RB-Y1 + RoboEra X-Hands, retains human-like dexterous manipulation, demonstrating RLWRLD's hardware-agnostic RFM in a live task. Main Application: Contact-rich manipulation for industrial and logistics settings (assembly, picking/packing), where one RFM redeploys across evolving hardware without per-robot retraining.
展品详情
RLWRLD focuses on the "last mile" of industrial automation — tasks that rigid, pre-programmed robots and today's general-purpose robot models still fail at. Core industry applications include precision assembly (e.g., bolt-fastening, connector/plug insertion), and logistics/fulfillment operations (item picking, sorting, packing, parts handling), where success depends on fine motor control rather than repetitive fixed motion.
Unlike models built for broad task generality, RLWRLD's RFM is dexterity-first: it is designed around five recurring failure modes seen in real industrial deployments — grasp diversity, spatial precision, temporal precision (reacting to moving objects), contact precision (using force/tactile signals, not just vision), and context awareness across multi-step tasks. This dexterity-centered design is what allows the model to reliably perform unstructured, contact-rich manipulation that vision-only or motion-scripted automation cannot handle